Chatomatic — AI Assistant SaaS
Chatomatic lets businesses train an AI assistant on their own content and embed it anywhere. I co-founded it, launched to 100+ users, then rebuilt the entire platform solo — ~25K LOC across dashboard, playground, API, and an embeddable widget.
01 — Problem
Answers people can trust
Generic chatbots hallucinate. For a business assistant, a confident wrong answer about pricing or policy is worse than no answer. The product bet: retrieval-grounded responses with visible citations, embedded on any website with one script tag.
As co-founder I owned the entire technical side — architecture, API, dashboard, embed widget, and the RAG pipeline.
02 — Retrieval
Hybrid RAG with a fallback
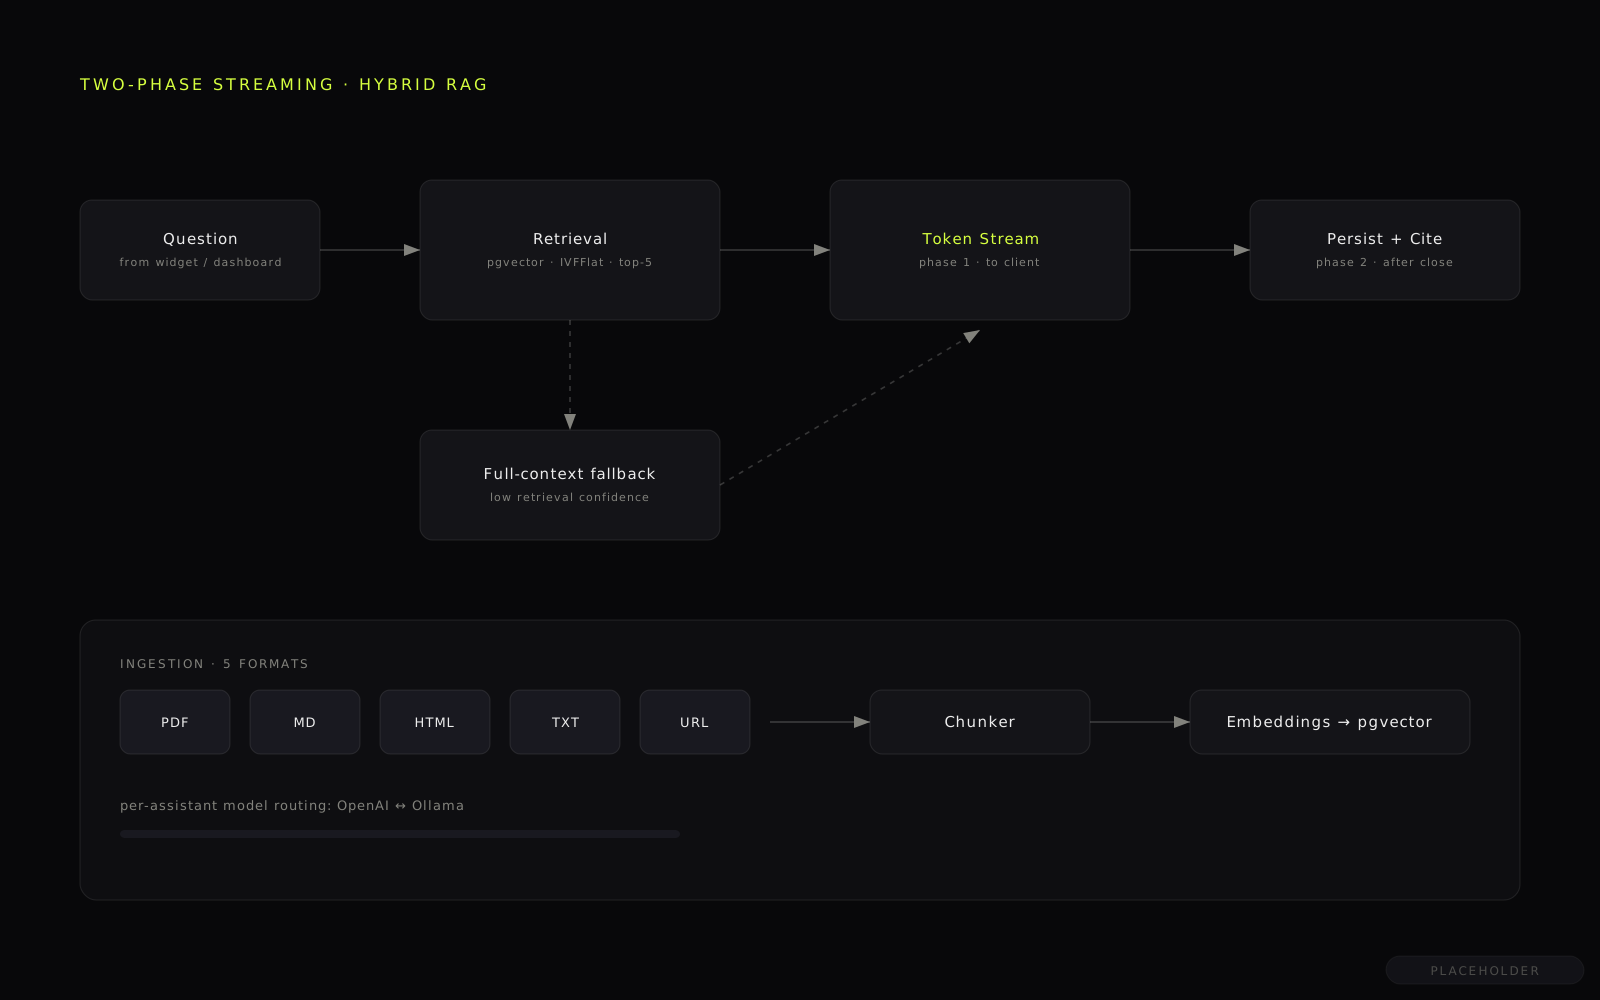
Ingestion accepts 5 formats, chunks them, and stores embeddings in PostgreSQL with pgvector under an IVFFlat index. At question time the pipeline retrieves the top-5 chunks — but small knowledge bases defeat vector search, so when retrieval confidence is low the pipeline falls back to full-context: pass everything, let the model decide.
Citations are first-class: every answer carries inline numbered references back to source chunks, so users can verify instead of trusting.
03 — Knowledge
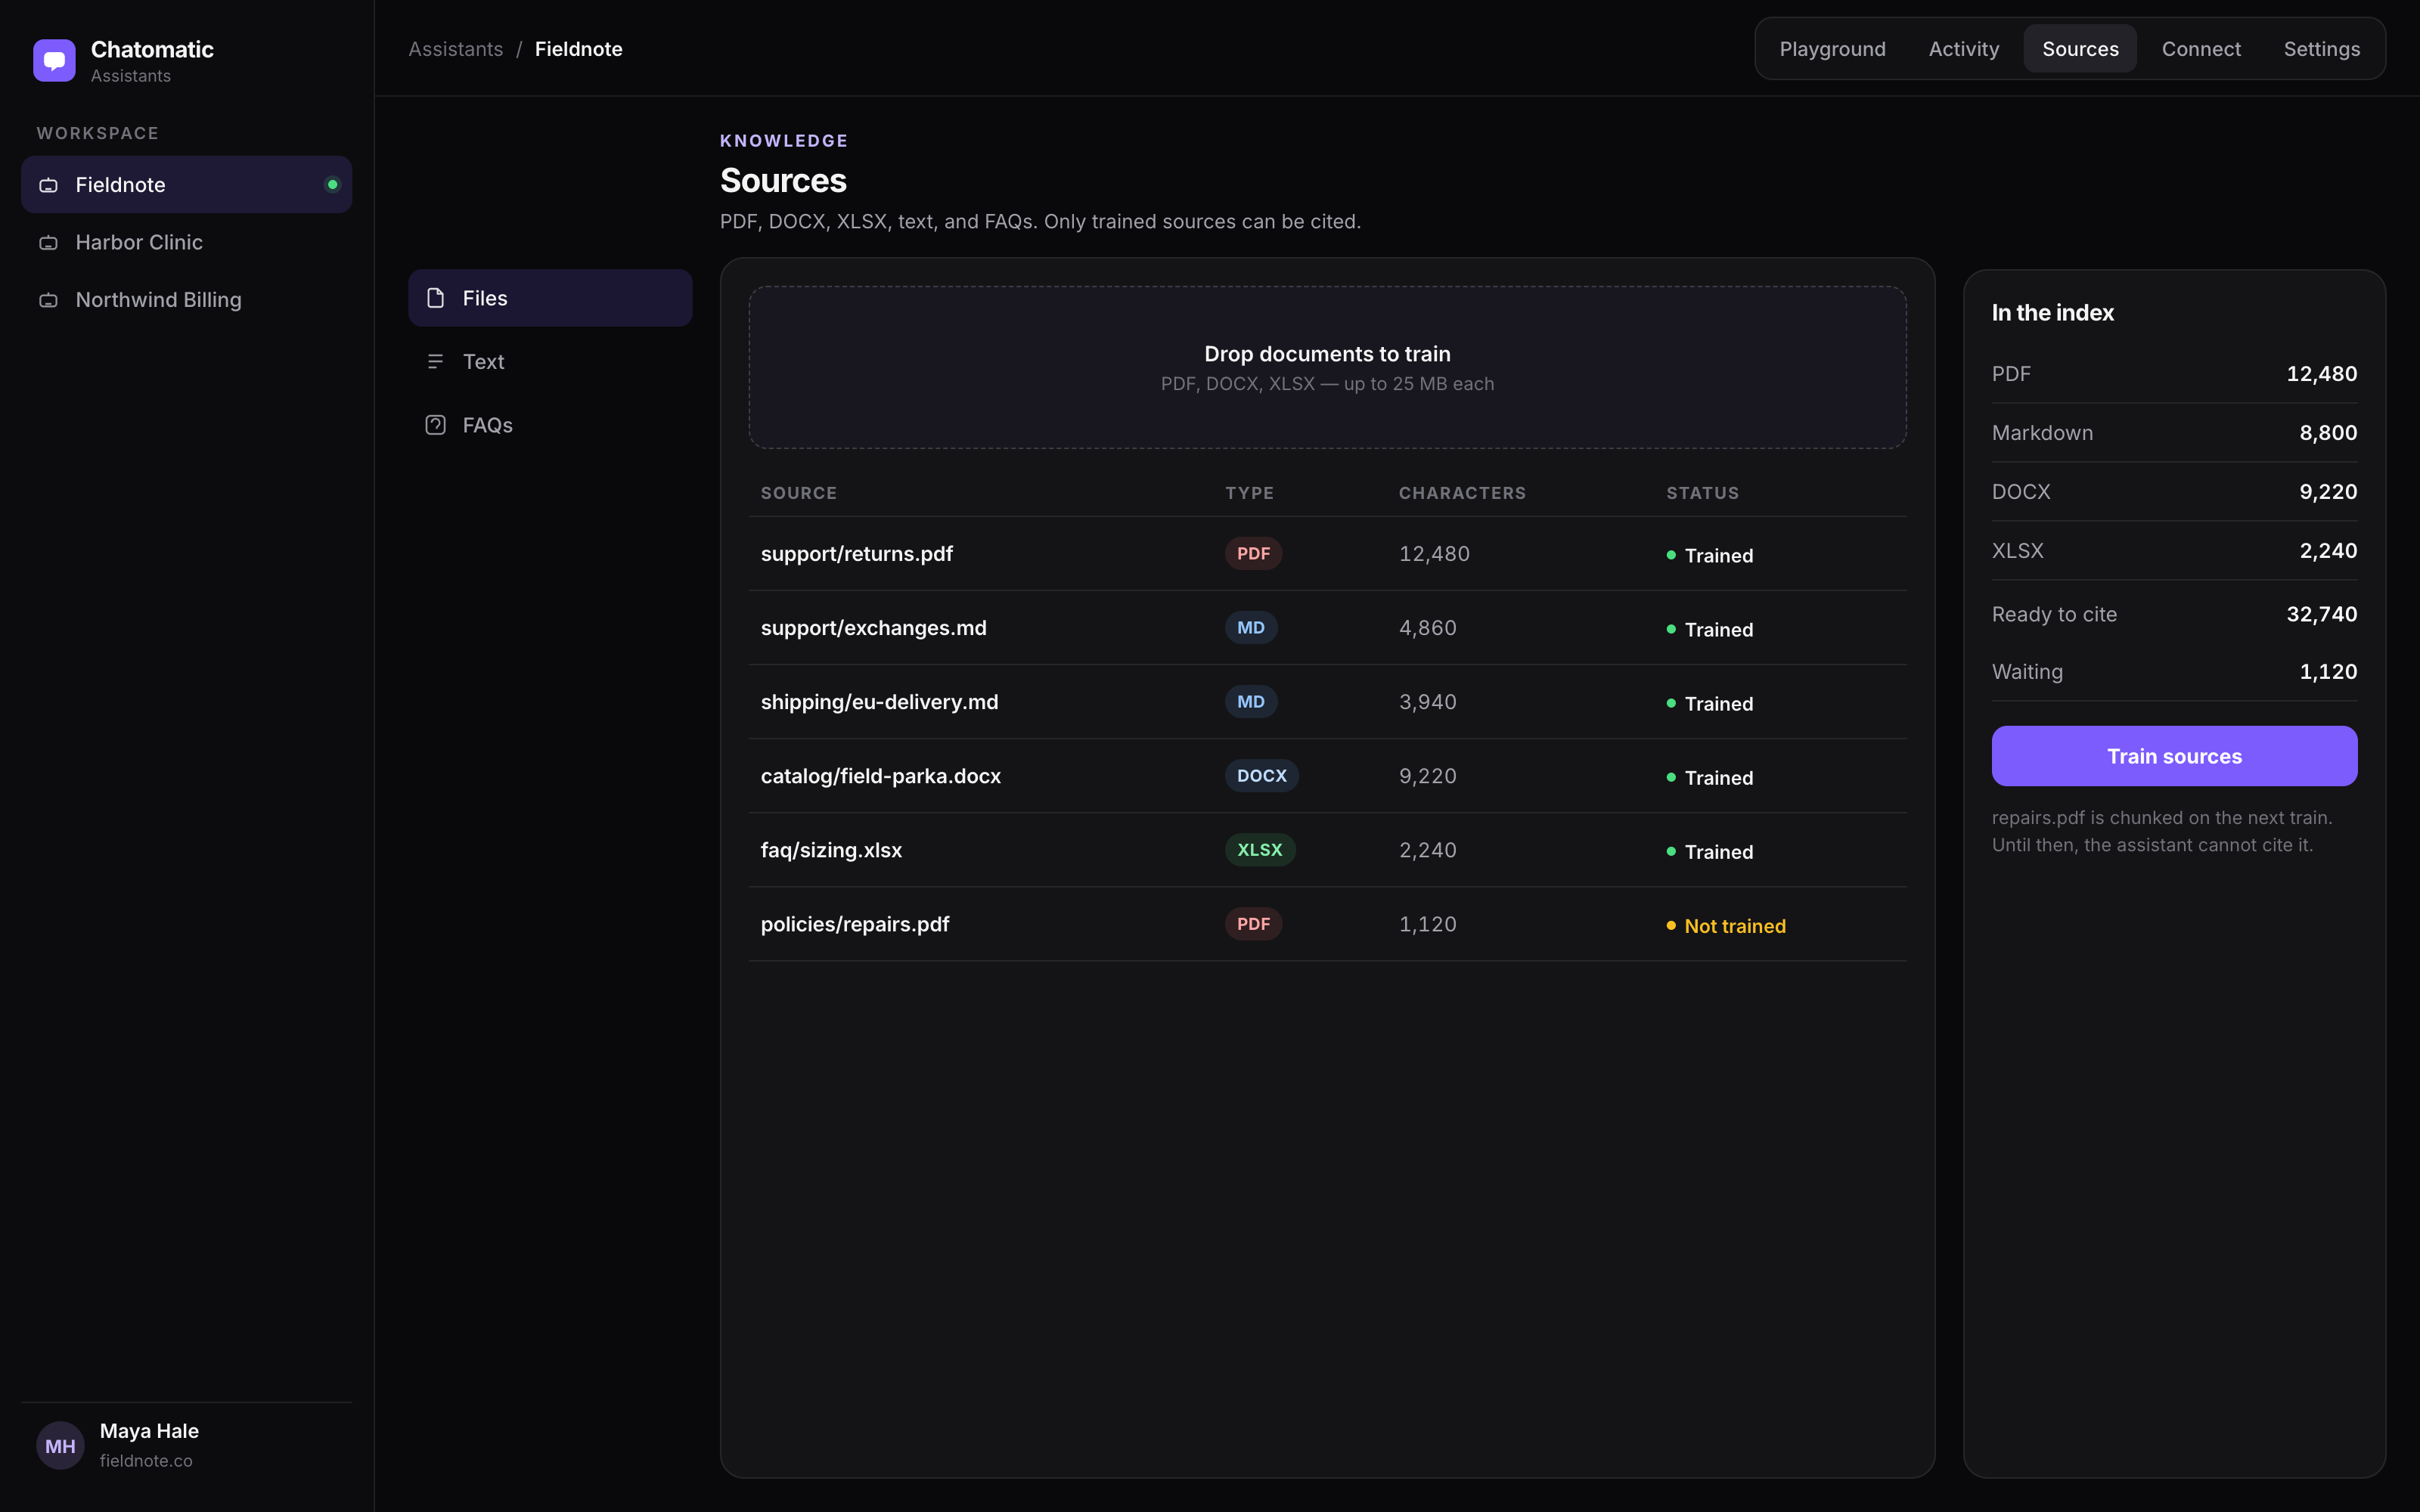
Five formats, one index
A source the assistant has not been trained on cannot be cited. PDF, DOCX, XLSX, Markdown, and FAQs land in the same index, with character counts for what is ready and what is still waiting.
04 — Streaming
Two-phase streaming chat
Streaming and persistence fight each other: you want tokens on screen immediately, but citations aren't final until the stream ends. The pipeline runs in two phases — phase one retrieves and streams tokens to the client; phase two, after the stream closes, persists the message with its citation set atomically. The user sees a live answer; the database only ever sees a complete one.
The API is a greenfield Fastify service: 7 modules, 27 Result-typed use-cases (no thrown business errors — every failure is a typed value), 11 tables, public embed routes, and per-assistant routing between OpenAI and Ollama.
05 — Embed
A widget that survives any website
The embeddable widget renders inside Shadow DOM, so host-page CSS can't leak in and widget styles can't leak out. It's built with Vite and bundled with Rollup into a single self-contained script — one tag, any site, no iframe jank.
06 — Outcome
Launch, and the harder second version
V1 launched to 100+ users. The 2026 rebuild — done solo — replaced the entire stack with the architecture above (~25K LOC), turning a launched MVP into a platform: dashboard, playground, typed API, and an embed that businesses can install in a minute.
Building the same product twice taught me more about system design than any job could: the second version is what the first one should have been, and I have the diff to prove it.
Stack
Next case
No-Code App Builder→